This open source Python library provide several solvers for optimization problems related to Optimal Transport for signal, image processing and machine learning.
Write up the current RCSNN results and create slides for tomorrow’s presentation with Rukan
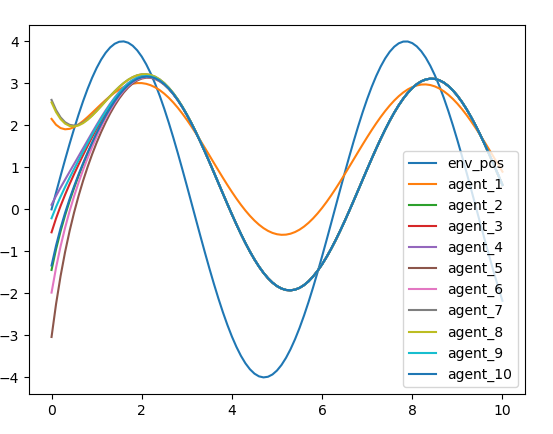
I think that the error calculation should be a statistical measure of the divergence over a given window, which could include the entire prediction, but would otherwise be a tail of n
The average error
The variance (std dev, etc)
Outliers (e.g. rare, BIG errors)
Linear regression calc for error and variance
The reason that I think that this matters is that a prediction could have occasional large errors but otherwise be good, and we need a way to know that and characterize our results
GPT Agents
Getting back up to speed on Jarod’s work, which looks amazing.
Given the computational cost and technical expertise required to train machine learning models, users may delegate the task of learning to a service provider. We show how a malicious learner can plant an undetectable backdoor into a classifier. On the surface, such a backdoored classifier behaves normally, but in reality, the learner maintains a mechanism for changing the classification of any input, with only a slight perturbation. Importantly, without the appropriate “backdoor key”, the mechanism is hidden and cannot be detected by any computationally-bounded observer. We demonstrate two frameworks for planting undetectable backdoors, with incomparable guarantees.
First, we show how to plant a backdoor in any model, using digital signature schemes. The construction guarantees that given black-box access to the original model and the backdoored version, it is computationally infeasible to find even a single input where they differ. This property implies that the backdoored model has generalization error comparable with the original model. Second, we demonstrate how to insert undetectable backdoors in models trained using the Random Fourier Features (RFF) learning paradigm or in Random ReLU networks. In this construction, undetectability holds against powerful white-box distinguishers: given a complete description of the network and the training data, no efficient distinguisher can guess whether the model is “clean” or contains a backdoor.
Our construction of undetectable backdoors also sheds light on the related issue of robustness to adversarial examples. In particular, our construction can produce a classifier that is indistinguishable from an “adversarially robust” classifier, but where every input has an adversarial example! In summary, the existence of undetectable backdoors represent a significant theoretical roadblock to certifying adversarial robustness.
Book
Work on the interview section. Ask about forms of bias, and how using the machine to find bias could help uncover patterns of it in humans as well. The idea of asking the same question a thousand times and getting a distribution of answers. Done! At least the first draft
Add something to the Epilogue about the tension between authoritarian and egalitarian governments
Play around with titles
SBIRs
9:00 ITM discussion
Continue code generation. Need to make the BoardMonitor and BoardMonitorChild classes, then start running/stepping code within tool. I’d like to figure out tabs so that the JSON and hierarchy views could share the same screen space. Done!
Progress!
And remarkably, everything still works. Need to wire up the output of the dictionary
GPT Agents
Make a flier, email, and informed consent
Poke around at getting more technical keywords for things like science papers
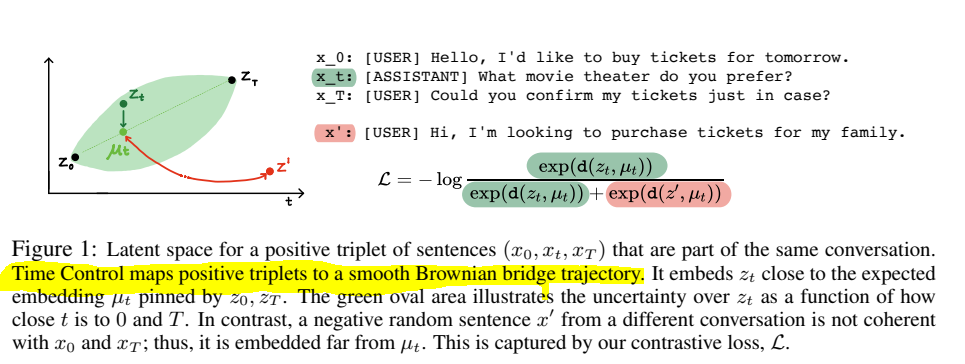
Modern language models can generate high-quality short texts. However, they often meander or are incoherent when generating longer texts. These issues arise from the next-token-only language modeling objective. To address these issues, we introduce Time Control (TC), a language model that implicitly plans via a latent stochastic process. TC does this by learning a representation which maps the dynamics of how text changes in a document to the dynamics of a stochastic process of interest. Using this representation, the language model can generate text by first implicitly generating a document plan via a stochastic process, and then generating text that is consistent with this latent plan. Compared to domain-specific methods and fine-tuning GPT2 across a variety of text domains, TC improves performance on text infilling and discourse coherence. On long text generation settings, TC preserves the text structure both in terms of ordering (up to +40% better) and text length consistency (up to +17% better). Human evaluators also prefer TC’s output 28.6% more than the baselines.
Book
Finished(?) definitions
Moved “Interview with a Biased Machine” to the beginning of the Practice section. Going to work on that next
SBIRs
Get the lit review slides together for after the standup – done!
9:15 standup
More code generation
Finish breaking bdmon into a class. As I do this, I think that it might make sense to have two directories – the directory that contains the editable child classes and a directory under that one that contains the generated files that are created each time the tool runs. Done!. This would allow the BoardMonitor class to have a decision_process() method that gets overridden easily in a child class. Next.
Dynamically calculate the import lib.
Wire up the run and step buttons
Terminate() should write things out? Done
Meeting with Ron about Crossentropy
GPT Agents
Figured out how to start find the Kuali IRB process and got some things down. Will need to walk through some things at the 3:30
Two purposes – understanding the SoA, and finding a gap. This requires critical thinking, and an understanding of the problems, not just appeals to authority
Truthiness != trustworthiness
Wikipedia, Google, GScholar, and Elicit
Also blog posts, videos, etc.
Look at cites. Large counts are good! Search within citing
Look at authors. Sort by date. Is this recent?
Look for survey papers
Finding terms to search on is hard. Do not assume that you have the right ones at first.
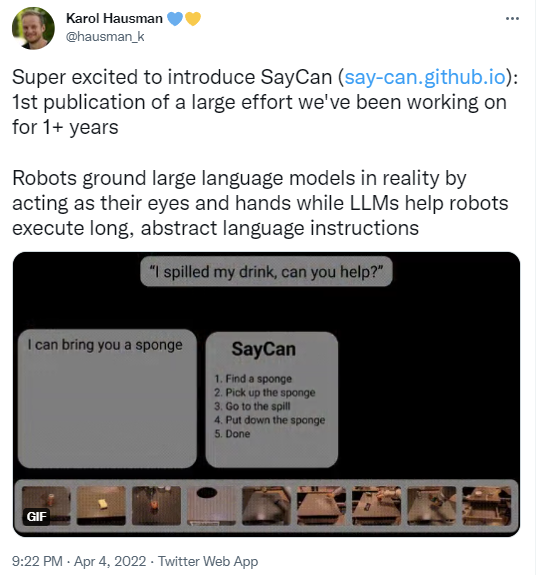
Language model networks
Code generation
The subclassed code works!
Working on executing Python within python. It’s surprisingly easy. You can import the file/class, and then refer to it:
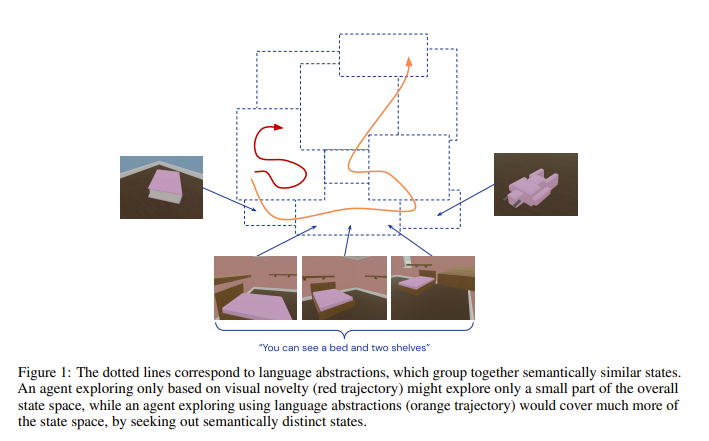
Continuous first-person 3D environments pose unique exploration challenges to reinforcement learning (RL) agents because of their high-dimensional state and action spaces. These challenges can be ameliorated by using semantically meaningful state abstractions to define novelty for exploration. We propose that learned representations shaped by natural language provide exactly this form of abstraction. In particular, we show that vision-language representations, when pretrained on image captioning datasets sampled from the internet, can drive meaningful, task-relevant exploration and improve performance on 3D simulated environments. We also characterize why and how language provides useful abstractions for exploration by comparing the impacts of using representations from a pretrained model, a language oracle, and several ablations. We demonstrate the benefits of our approach in two very different task domains — one that stresses the identification and manipulation of everyday objects, and one that requires navigational exploration in an expansive world — as well as two popular deep RL algorithms: Impala and R2D2. Our results suggest that using language-shaped representations could improve exploration for various algorithms and agents in challenging environments.
Tasks
Mulch and edging
Fortunately, taxes are already done!
Maybe get started on chores
SBIRs
Send text to JHU – done! But they aren’t going for it
Code generation
Made some buttons that trigger non-functional callbacks
Moved some text around to the beginning GPT interview and took it out of the influence/dominance/attention section. I had to rework that a bit to include egalitarianism and inverse dominance
Trying to figure out how to finish up the deep bias chapter. I’d like to do something that shows how these patterns play out in modern politics. Maybe the difference between suppression and cancelling
1:00 Meeting! It went well, I think. KH is a textbook company, so it’s probably not a good fit but 1) I found a way to talk to publishers! and 2) They will take a look at the proposal and make suggestions (maybe?)
Starting to finish up Deep Bias chapter. Maybe move it to the front? My thinking is to introduce the human tension between hierarchy and egalitarianism, then communication technology (phase locking), then iteratively revisit?
SBIRs
Meeting with Steve – done
Sprint planning – done
Write up notes from yesterday
Set up MDA meeting for next week?
GPT-Agents
3:30 Meeting
Since ASRC is unwilling to be lead, do we write a proposal? Find a lead?
I had an interesting dream last night. Someone had invented a type of hybrid self driving car. It used a joystick, that could be set for left or right handed people. In manual mode, it worked like a regular joystick – forward accelerates, left and right steer, backwards brakes or reverses. In “self driving” mode, the joystick had nine detents. Pushing it into the fwd detent would autodrive in a lane. Nudging left or right would set up lane changes.
In city driving, putting it in the side detents would set up signaling and sensors for a turn. Going forward into one of the corners would initiate the turn. Parking was initiated by pulling up next to a space and then using the rear corner detent. It was a pretty cool system. I think in the dream the system was prototyped by the child of Mexican field workers who prototyped it on their parent’s pickup truck.
Tasks
Call Aluminess – done! Ships by the end of the week?
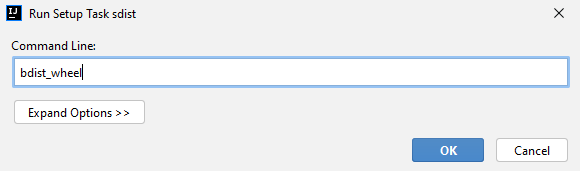
Work some more on deploying Keyword Explorer – done! Here’s how you deploy using JetBains PyCharm
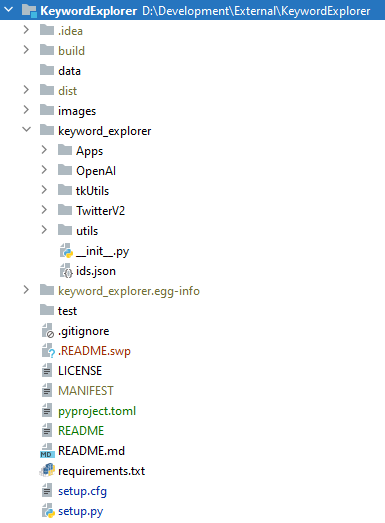
First, make sure you have up-to-date versions of setuptools and twine. Also make sure your directory looks something like this:
Create your setup.cfg file
[metadata]
description-file = README.md
name = keyword_explorer
Then, your setup.py file. It is important to explicitly list the subdirectories in the packages array. Here’s my example (Note that “long_description) is a variable. It is what PyPI uses to create its description, and needs to be updated before creating the wheel. (see here for an example):
from  distutils.core import  setup

setup(
    name='keyword_explorer',
    version= "0.0.3.dev",
    packages=['keyword_explorer',
              'keyword_explorer.utils',
              'keyword_explorer.TwitterV2',
              'keyword_explorer.tkUtils',
              'keyword_explorer.OpenAI',
              'keyword_explorer.Apps'],
    url='https://github.com/pgfeldman/KeywordExplorer',
    license='MIT',
    author='Philip Feldman',
    author_email='phil@philfeldman.com',
    description='A tool for producing and exploring keywords',
    long_description= long_s,
    install_requires=[
        'pandas~=1.3.5',
        'matplotlib~=3.2.2',
        'numpy~=1.19.5',
        'sklearn~=0.0',
        'scikit-learn~=0.24.2',
        'requests~=2.27.1',
        'wikipedia~=1.4.0',
        'openai~=0.11.5',
        'networkx~=2.6.2',
        'tkinterweb~=3.12.2'],

    classifiers=[  # Optional
        # How mature is this project? Common values are
        #   3 - Alpha
        #   4 - Beta
        #   5 - Production/Stable
        'Development Status :: 3 - Alpha',
        "Programming Language :: Python :: 3",
        "License :: OSI Approved :: MIT License",
        "Operating System :: OS Independent",
    ],
)
NEW! As of June 1, 2023, PyPi requires 2FA and tokens to upload:
Set your username to __token__
Set your password to the (long!) token value, including the pypi- prefix (e.g. pypi-AgEIcHl…)
Where you edit or add these values will depend on your individual use case. For example, some users may need to edit their .pypirc file, while others may need to update their CI configuration file (e.g. .travis.yml if you are using Travis).
Advanced users may wish to inspect their token by decoding it with base64, and checking the output against the unique identifier displayed on PyPI.








You must be logged in to post a comment.