Category Archives: Phil

Phil 5.13.21

Normally, I’d be doing my plots of COVID deaths for the month of April, but the disease is now working its way through countries that are not accurately reporting counts. I heard today on the BBC that India’s counts could be 2-8 times higher than reported.

GPT Agents

  • Good Gephi filters tutorial
  • After making a bunch of maps yesterday, and in particular, struggling with the conspiracy theory map that has no useful Wikipedia ground truth to eliminate cruft, I realize I’m going to have to build a more interactive tool. It should be useful for other things, like Antonio’s concept mapper. It can also support multiple prompts, like
    • “A short list of {}”
    • “A short list of {} that are similar to {}”
    • “A short list of the elements that make up {}”
  • The human chooses the nodes that make sense, and intermediate networks are drawn at each pass through the results. The exit is manual, and writing out a gml file can happen at any time
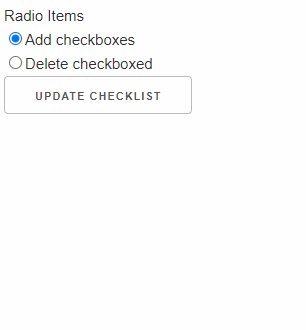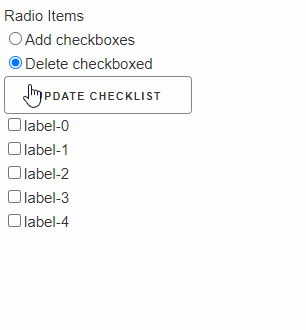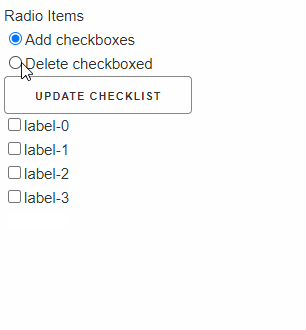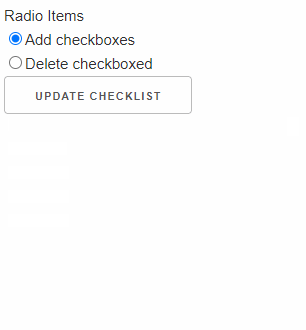
  • Going to try Plotly for this. If I can make dynamic lists of checkboxes, then I should be ok, otherwise TKinter
    • Making progress with Plotly!
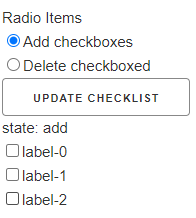
Dynamically adding checkboxes!
  • Got everything working! Going to make it a class now
  • 5:00 Meeting

SBIR

  • 9:15 Standup
  • Meet with Rukan after to see how things are going
  • Create final report template with material from previous reports
  • Set up meeting with Clay to discuss commercialization strategy
Phil 5.12.21

SBIR

  • 9:30 Meeting with Rukan to see what our results are from the overnight runs
  • 10:00 Group meeting. Need to discuss proposal and share Overleaf template

GPT Agents

  • Still filling up the Yelp db. Currently at around 500,000 reviews
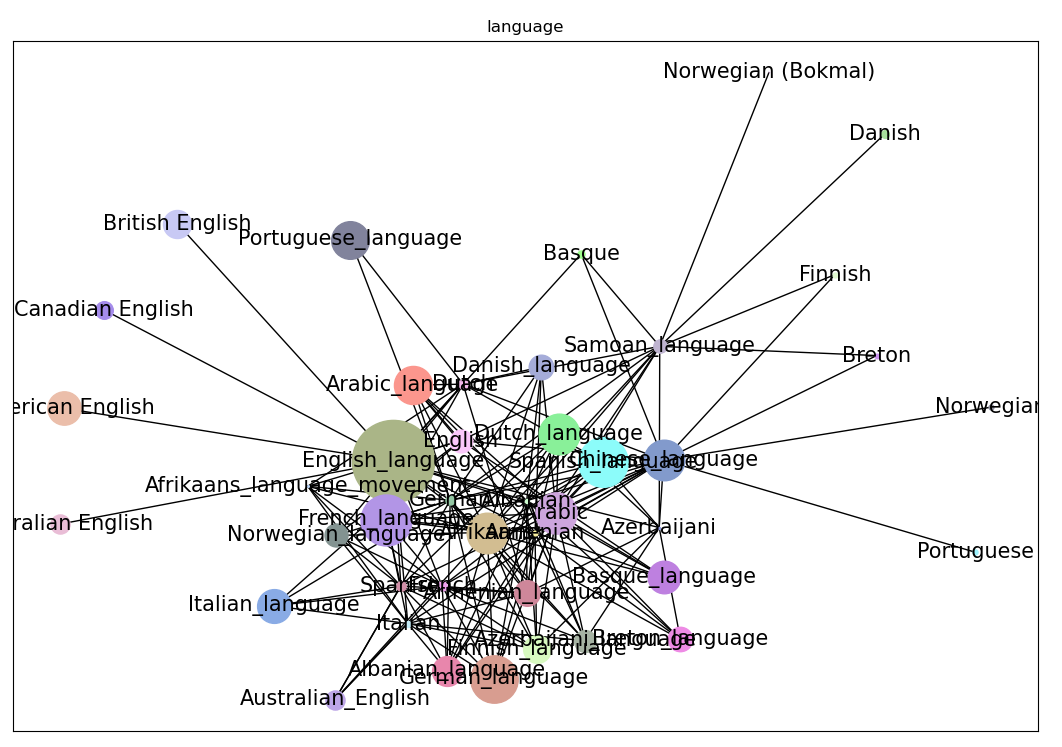
  • Language map – Send a copy to Andreea when done. This one is based on the same repeated prompt, because I screwed up the template code
https://viztales.com/wp-content/uploads/2021/05/image-2.png
  • Language map using seeds of English, Chinese, and Samoan
https://viztales.com/wp-content/uploads/2021/05/language_3.png
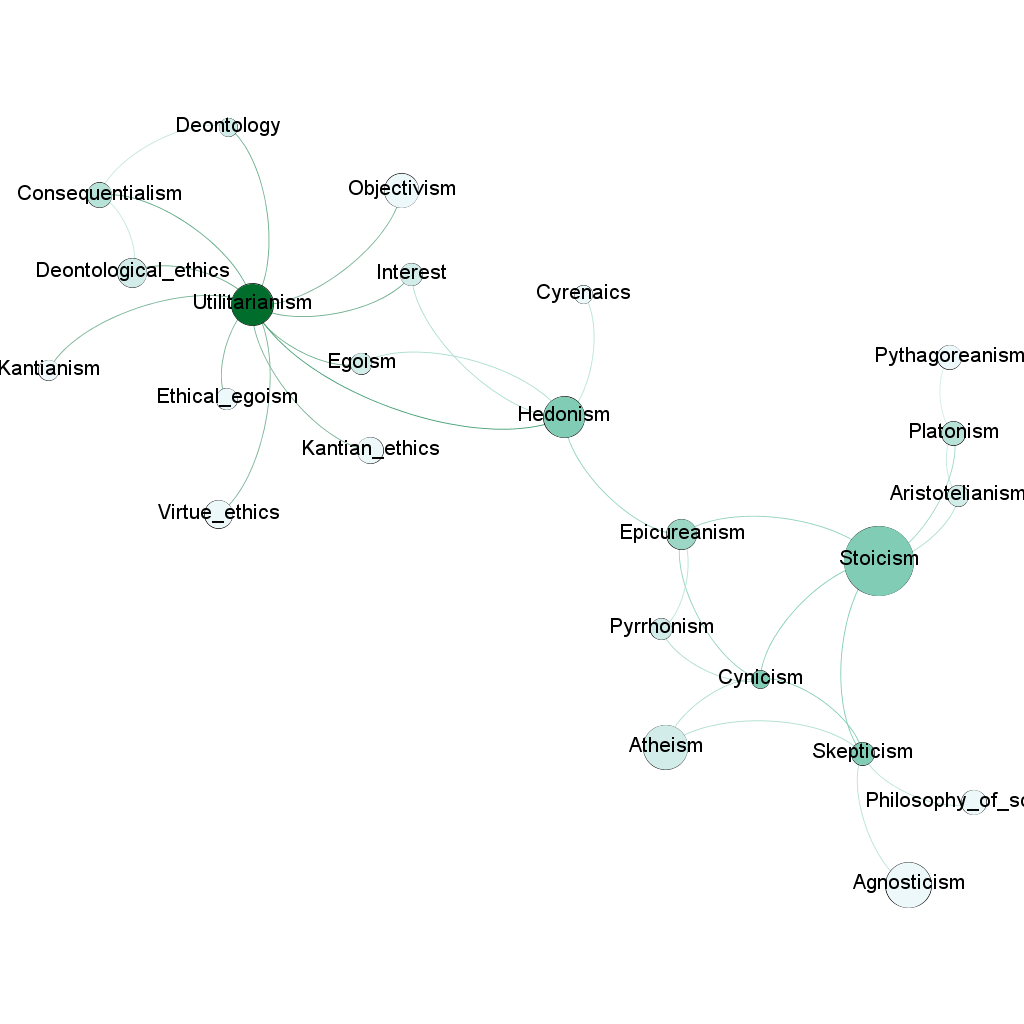
  • Philosophy Map using seeds of Utilitarianism and Hedonism
https://viztales.com/wp-content/uploads/2021/05/philosophy_1.png
  • Food Map using seeds of Pasta, Hamburger, Lettuce, Avocado and Cheese
https://viztales.com/wp-content/uploads/2021/05/food_3-1.png
  • Conspiracy theories seeded with “vaccines cause autism”
https://viztales.com/wp-content/uploads/2021/05/conspiracy_1-2.png

JuryRoom

  • 7:00 Meeting

Phil 5.11.21

Deep Learning applications for COVID-19

This survey explores how Deep Learning has battled the COVID-19 pandemic and provides directions for future research on COVID-19. We cover Deep Learning applications in Natural Language Processing, Computer Vision, Life Sciences, and Epidemiology. We describe how each of these applications vary with the availability of big data and how learning tasks are constructed. We begin by evaluating the current state of Deep Learning and conclude with key limitations of Deep Learning for COVID-19 applications. These limitations include Interpretability, Generalization Metrics, Learning from Limited Labeled Data, and Data Privacy. Natural Language Processing applications include mining COVID-19 research for Information Retrieval and Question Answering, as well as Misinformation Detection, and Public Sentiment Analysis. Computer Vision applications cover Medical Image Analysis, Ambient Intelligence, and Vision-based Robotics. Within Life Sciences, our survey looks at how Deep Learning can be applied to Precision Diagnostics, Protein Structure Prediction, and Drug Repurposing. Deep Learning has additionally been utilized in Spread Forecasting for Epidemiology. Our literature review has found many examples of Deep Learning systems to fight COVID-19. We hope that this survey will help accelerate the use of Deep Learning for COVID-19 research.

Word embeddings quantify 100 years of gender and ethnic stereotypes

Word embeddings are a powerful machine-learning framework that represents each English word by a vector. The geometric relationship between these vectors captures meaningful semantic relationships between the corresponding words. In this paper, we develop a framework to demonstrate how the temporal dynamics of the embedding helps to quantify changes in stereotypes and attitudes toward women and ethnic minorities in the 20th and 21st centuries in the United States. We integrate word embeddings trained on 100 y of text data with the US Census to show that changes in the embedding track closely with demographic and occupation shifts over time. The embedding captures societal shifts—e.g., the women’s movement in the 1960s and Asian immigration into the United States—and also illuminates how specific adjectives and occupations became more closely associated with certain populations over time. Our framework for temporal analysis of word embedding opens up a fruitful intersection between machine learning and quantitative social science

How to make a racist AI without really trying

SBIR

  • Sprint planning – I’m going to be busy
  • More work with Rukan. We’re going to focus on some simple spikes
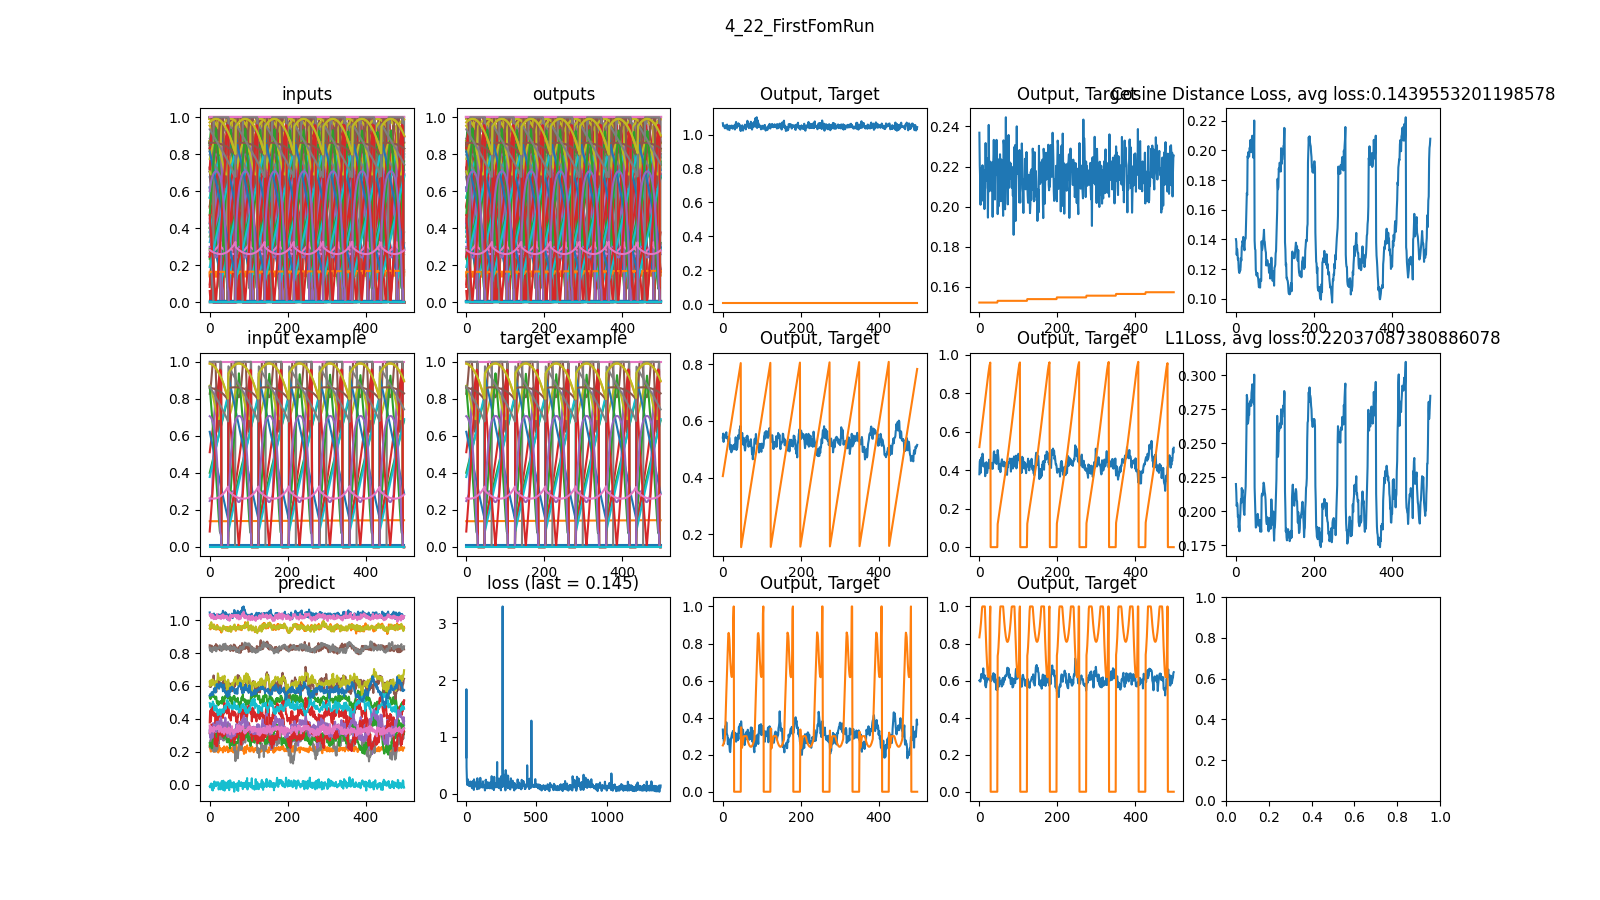
    • The simple spikes look great. We’re going to do a sensitivity analysis on the MDS data now
  • Got my fancy query working
create or replace view view_combined as
select distinct e.id, e.name, e.description, s1.value as dimension_size, s2.value as layers,
r1.value as avg_cos_loss, r2.value as avg_l1_loss from
table_experiment e
join table_settings s1 on e.id = s1.experiment_id and s1.name = 'dimension_size'
join table_settings s2 on e.id = s2.experiment_id and s2.name = 'layers'
join table_results r1 on e.id = r1.experiment_id and r1.name = 'avg cosine loss'
join table_results r2 on e.id = r2.experiment_id and r2.name = 'avg l1 loss';
select * from view_combined where id = 100;

GPT-Agents

Phil 5.10.21

3:00 Dentist

GPT-Agents

  • Yelp parser
  • Try maps of food, fashion(!), movies, books, politicians, etc?
  • 4:30 meeting with Andreea

SBIR

  • Make slides for sprint review
  • Sprint review

Phil 5.5.21

GPT-Agents

  • Update and submit paper (ArXiv and SocialSens) – done!

SBIR

  • Phase 2 proposal kickoff
  • Weekly tagup
  • AI/ML tagup (mention paper acceptance)

Book

  • Continue rolling in changes

JuryRoom

  • Worked on the intro to Pryvank’s paper
  • 7:00 Meeting

Phil 5.4.21

Amazing Animated Star Wars Fighter Ships - Best Animations
May the Fourth be with you and all that

See if I can get this trailer – done!

SBIR

  • 9:15 status meeting. It looks like I’ll be working on the phase 2 proposal for the rest of the week?
  • 8:45 pre-standup with Rukan to see how things are going
    • Looks like we are going to improve our experiment pipeline since we seem to be loosing data. Rukan is looking into what it takes to get MySql installed on his instance

GPT Agents

  • 3:00 Meeting
  • I still haven’t entirely fixed my UTF 8 problem
  • Start writing up something about the belief maps to add to the chess paper, and maybe as an overall article
    • Country counts (150 vs 195 with no false positives, excluding six prompt countries, 76% coverage) Missing countries include Guadalupe, Guyana, Israel, Jordan, Lebanon, Madagascar, Liberia, Micronesia, Niger, Paraguay, Senegal, Sri Lanka, Tunisia, Uruguay, Venezuela, and Yemen
    • Religion counts?
    • New favorite map:
https://viztales.com/wp-content/uploads/2021/05/world_4.png
  • Central America insert
  • Compared with actual map

Book

  • Start working on edits
  • Send Chris email. Done!

Phil 5.3.21

Call about trailer! Sold, dammit

GPT-Agents

  • 10:00 Meeting with Antonio. Nice discussion on moving forward. He suggests using the mapper to create a meta-knowledge graphing tool that works along the lines of the Third Author approach, where an expert can influence and interactively edit the creation of the maps
  • Worked on my UTF-8 problem, but it’s still not fixed
  • New Religion Map
https://viztales.com/wp-content/uploads/2021/05/religion_3.png
  • New World Map
https://viztales.com/wp-content/uploads/2021/05/world_3.png
  • Good meeting with Andreea about metaphors. It was interrupted by some kind of alert, so we’ll finish next week.

SBIR

  • Went over Rukan’s progress, which is pretty nice, particularly for ensembles:
https://viztales.com/wp-content/uploads/2021/05/image.png
  • He’s going to do a big run tonight to see how more training helps
  • We also talked about adding multihead attention to the middle layers. We may do an experiment on that

Phil 4.30.21

April is almost over! And after a couple of summer-like days, we’re back to seasonal

GPT-Agents

  • 3:30 Meeting
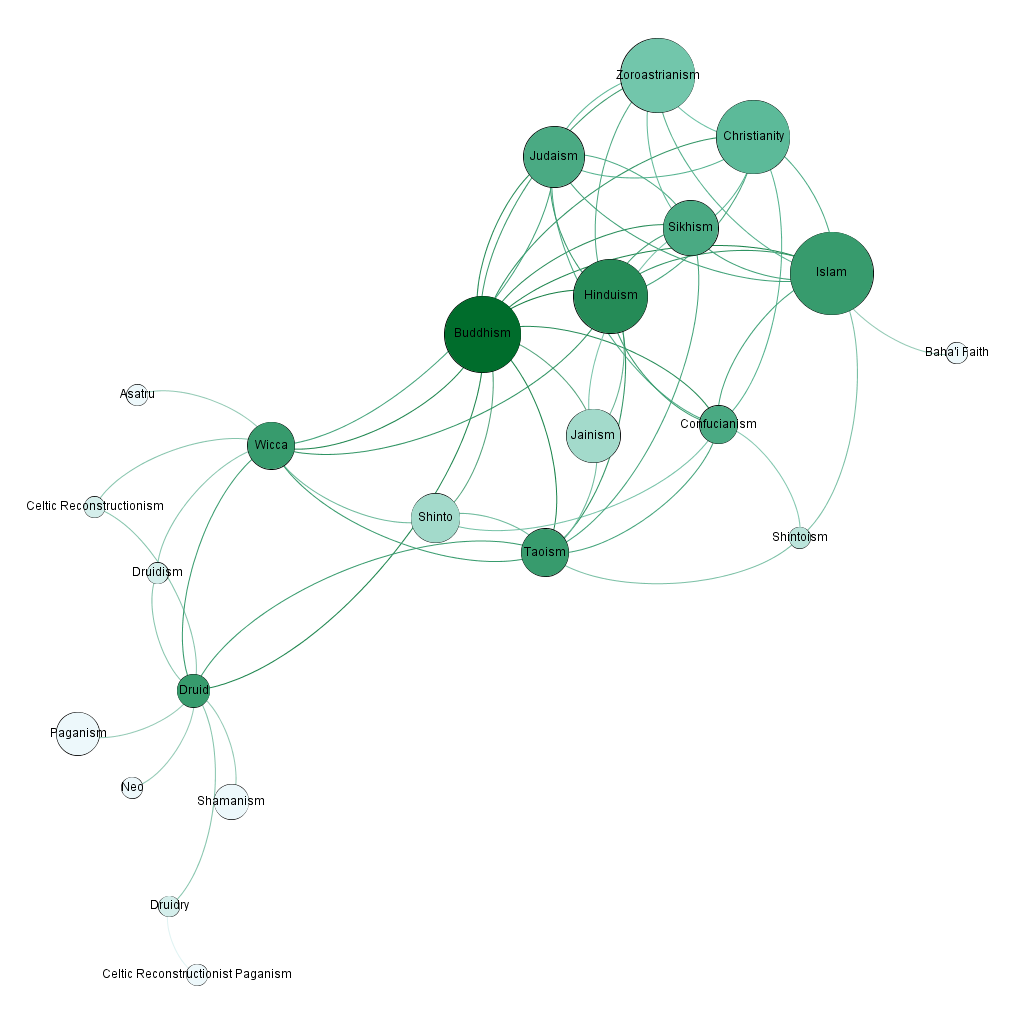
  • Working on a first pass at the religion map. Asking the GPT-3 for “A short list of religions:” returned a response that I regex’d into the following:
["Christianity", "Islam", "Hinduism", "Buddhism", "Judaism", "Sikhism", "Confucianism", "Shintoism", "Taoism", "Zoroastrianism", "Jainism", "Wicca"]
  • Next was getting the prompt:
"A short list of the religions that are closest to {}:"
  • working with the model. There are more varied responses, so the parsing is a little more complex. The way that I’m currently working is by having the model return ten (rather than 3) responses that I then organize:
    • The first element is to look for a similar Wikipedia page, which is done as follows:
source_term = "Seax Wicca"
page_list = wikipedia.search(source_term, suggestion=False)
print(page_list)
closest_list = dl.get_close_matches(source_term, page_list)
print(closest_list)

d = {}
total = 0
for p in closest_list:
views = get_wiki_pageviews(p)
d[p] = views
total += views

for k in d:
print("'{}' = {:,} views ({:.1f}%)".format(k, d[k], d[k]/total*100))
  • Which generates:
['Seax-Wica', 'Magical tools in Wicca', 'Raymond Buckland', 'Wicca', 'Wheel of the Year', 'Altar (Wicca)', 'History of Wicca', 'Triple Goddess (Neopaganism)', 'Horned God', 'Faery Wicca']
['Seax-Wica', 'Wicca', 'Faery Wicca']
'Seax-Wica' = 194 views (0.7%)
'Wicca' = 25,755 views (97.7%)
'Faery Wicca' = 417 views (1.6%)
  • I think for the time being, I’ll just pull the first one (closest_list[0]) and see what that looks like, though I could also use all close matches or the one with the largest page views
  • Rolling all the changes into GraphToDB. Urk.
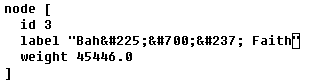
  • I had to tweak out some junk text (maybe UTF-8 issues?) Here’s an example: = “Baháʼí Faith” is being rendered as
https://viztales.com/wp-content/uploads/2021/04/religion_1.png
  • Here’s a bigger one:
https://viztales.com/wp-content/uploads/2021/04/religion_2.png

Book

  • 2:00 Meeting with Michelle. Nice progress!
  • 5:00 Meeting With Chris C. That was a really nice chat!
    • Need to write up a paragraph about me and my work.

Phil 4.29.21

SBIR

  • Finish writing and send on for review/submission
    • Summary – done!
    • Incorporate Peter & Loren’s contributions – done!
    • Looks good to submit tomorrow
    • 9:15 standup
    • 10:30 prep meeting
    • 3:00 intro meeting
      • Went nowhere. More than anything, this reminded me of a Defense with a hostile faculty lobbing hand grenades. In my list of management types, this guy was an assassin/power broker

GPT Agents

  • Got a ping from Ashwag on her team’s work, which was nice
    • Did some cleanup editing on the paper
  • Work on religion map if I get all the SBIR work done in time. Nope – tomorrow

Phil 4.28.21

https://www.nytimes.com/interactive/2020/world/asia/india-coronavirus-cases.html?action=click&module=Top%20Stories&pgtype=Homepage

GPT-Agents

  • Spent some time this morning adjusting the code so that experiment-specific regexes can be created and stored in the db. Also played around some with trying to figure out how to choose the best Wikipedia page(s?)

SBIR

  • Working on the status report. Mostly done. Need to do the summary paragraph
  • 2:00 weekly meeting. Asked Peter and Loren to supply content by COB Thursday

JuryRoom

  • 7:00 Meeting

Phil 4.27.21

GPT Agents

  • Did a little housecleaning since I’m going to have to work on the status report for the rest of the week. I’ve moved the experiment-specific code into its own method and added a “node_type”
  • Updated the ICWSM paper to include the NSF grant info
  • 3:00 Meeting
    • Spent a lot of time working on probes for belief systems such as white supremacy. It’s much more complex than countries. The parser needs(?) to be able to:
      • Split on \n as well as [,:;]
      • Ignore leading numbers
      • Match on earlier sections of each text (maybe just cut everything else after n words?)
      • Do a more forgiving match on the wikipedia. For example, the probe: “The great religions are all characterized by” returns a list that contains “Belief in a Messiah or a prophet.” Sending that to the wikipedia returns [‘Messiah’, ‘Messiah in Judaism’, “Judaism’s view of Jesus”, ‘Prophets and messengers in Islam’, ‘Jesus in Islam’, ‘False prophet’, ‘Last prophet’, ‘Prophet’, ‘Al-Masih ad-Dajjal’, ‘Messianism’], while splitting off the first two words (which are common across all results) to create “a Messiah or a prophet.” returns [‘Messiah’, ‘Messiah Prophet’, ‘False prophet’, ‘List of Jewish messiah claimants’, ‘Messiah in Judaism’, “Judaism’s view of Jesus”, ‘Last prophet’, ‘Jesus in Islam’, ‘Al-Masih ad-Dajjal’, ‘Messiah Part I’]

SBIR

  • 9:15 Sprint planning
  • Read the docs that Clay wants me to check out
  • Work on status report
    • Redid the summary as a list of accomplishments that I now need to flesh out
    • Added all the images to the figures directory

NOAA

  • Records Management Training

Phil4.26.21

GPT-Agents

  • Save GML – done!
  • Run multiple responses – done!
  • Save experiments – done!
  • I have a fancy world map! This one is 4kx4x so you can zoom in quite far. It started at 
"A short list of countries that are nearest to United States, separated by commas:"

And worked its way out from that (e.g. “A short list of countries that are nearest to Canada, separated by commas:”). It looks like it had not worked its way over to Africa yet, and there is no Greenland.

https://viztales.com/wp-content/uploads/2021/04/world.png

SBIR

  • Sprint review – done
  • Start writing second report – not started

Phil 4.22.21

GPT-Agents

  • Getting familiar with my NetworkxGraphing class. I’m going to create the graph first, and then persist it
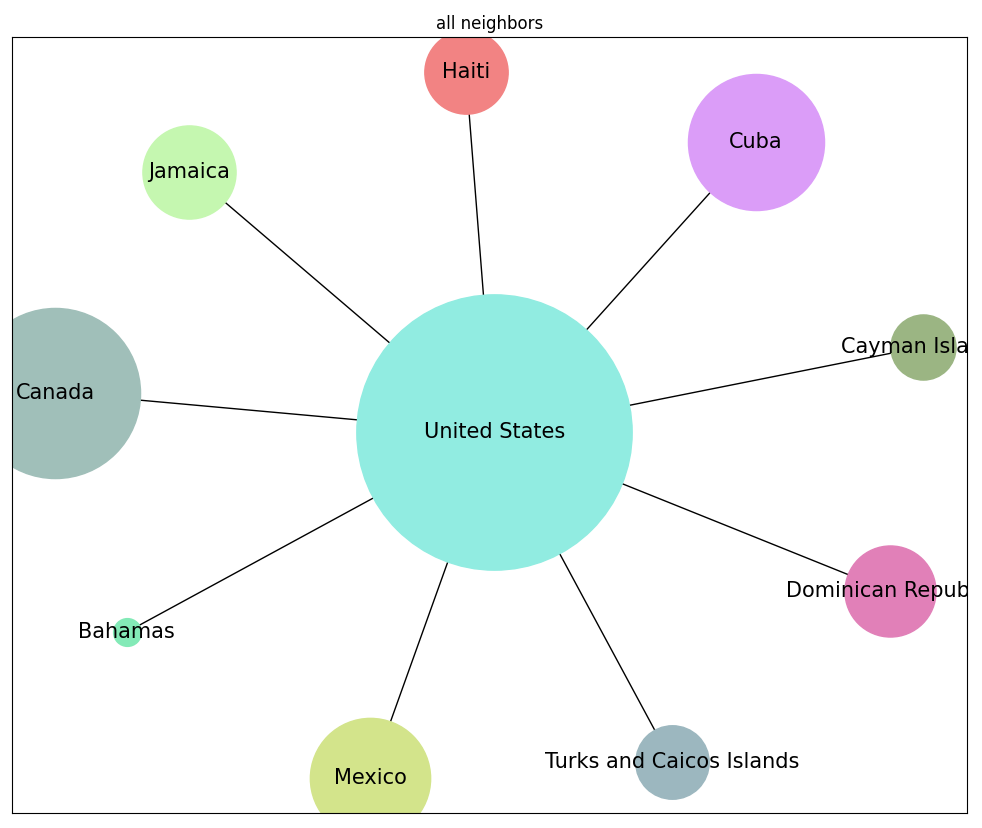
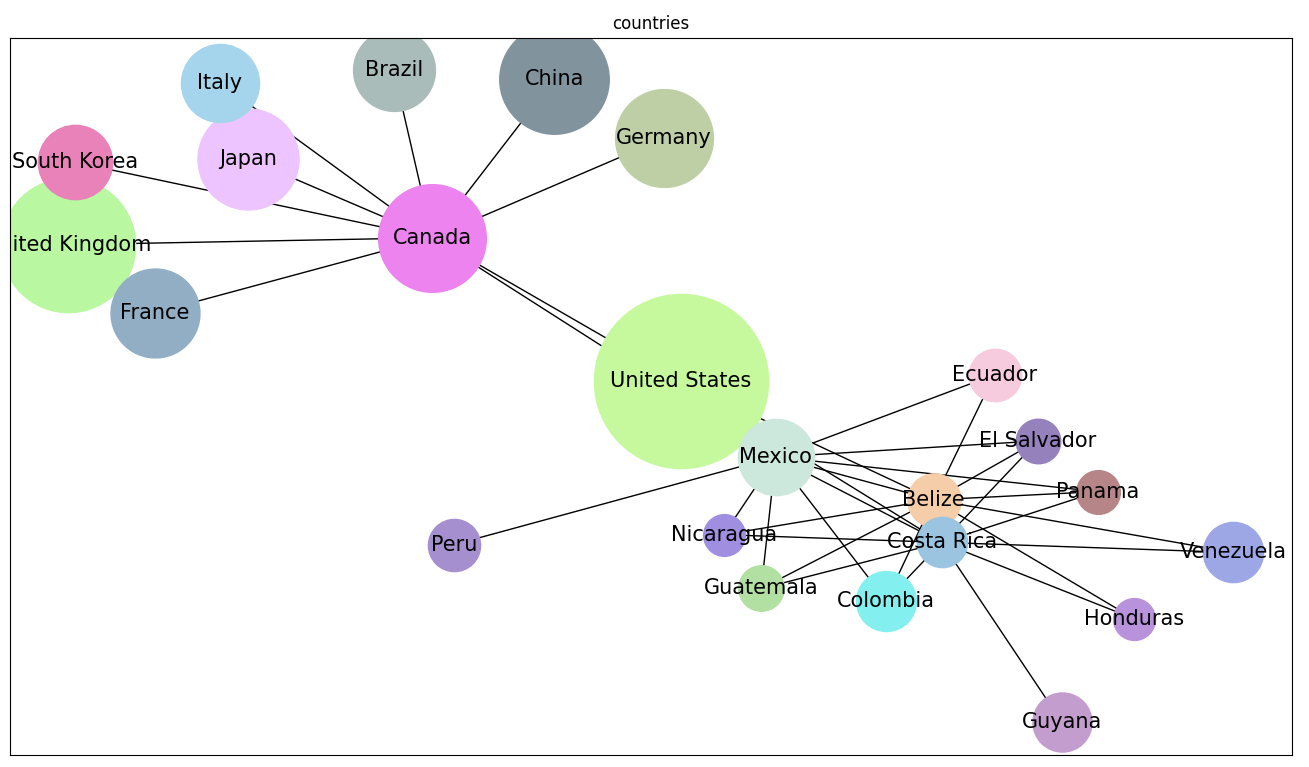
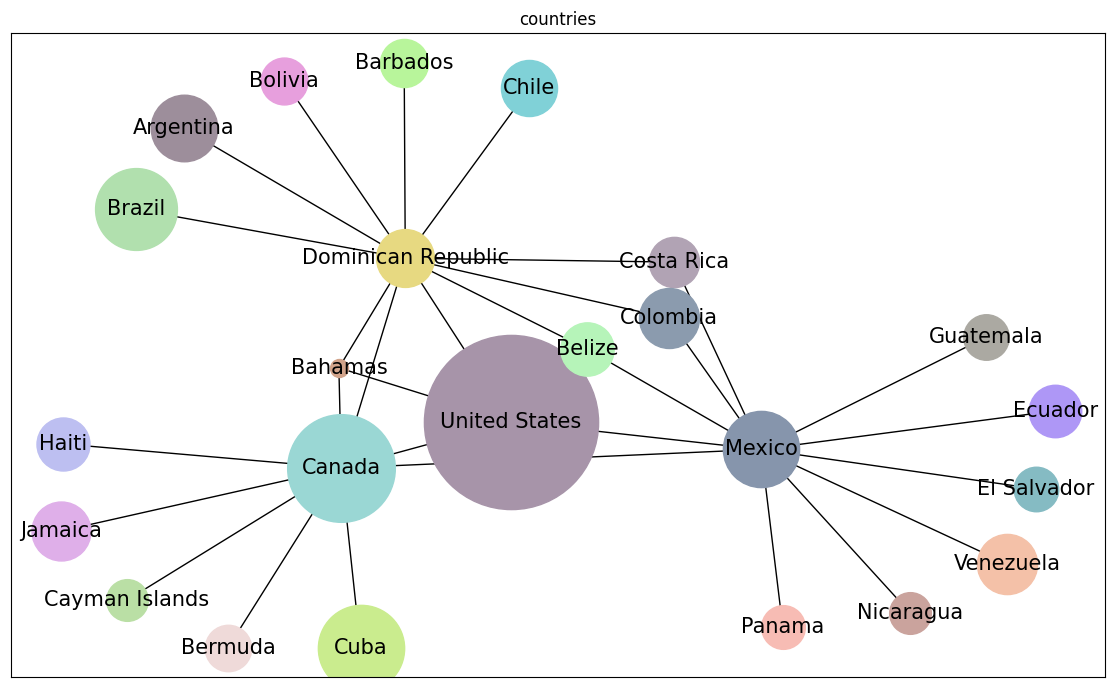
  • My very first map of “A short list of countries that are nearest to United States, separated by commas:”
  • Some more progress. This is one layer down, with no culling for likely nearest neighbors:
https://viztales.com/wp-content/uploads/2021/04/image-9.png
  • Here’s a nicer version:
https://viztales.com/wp-content/uploads/2021/04/image-10.png
  • Presentation to the data science team

SBIR

  • 9:15 standup
  • See how the ensemble turned out with the truncated inputs
  • Start on using MDS data. Having some issues:
https://viztales.com/wp-content/uploads/2021/04/image-11.png

3:30 presentation of the COVID work to a *dead* room. Sigh. But I got some slides done!