Category Archives: Phil

Phil 3.18.19

ASRC PhD 7:00 – 6:00

  • SlackToDb
    • Pull down text – Done, I hope. The network here has bad problems with TLS resolution. Will try from home
    • Link sequential posts – done
    • Add word lists for places and spaces (read from file, also read embeddings)
      • Writing out the config file – done
    • Add field for similarity distance threshold. Changing this lists nearby words in the embedding space. These terms are used for trajectory generation and centrality tables.
    • Add plots for place/space words
    • Add phrase-based splitting to find rooms. Buckets work within these splits. Text before the first split and after the last split isn’t used (For embedding, centrality, etc.)
    • Add phrase-based trimming. Test before one and after the other isn’t used
    • Stub out centrality for (embedded) terms and (concatenated, bucketed, and oriented) documents
    • Look into 3d for tkinter (from scratch)


    • Progress for the day:

SAGUI

Phil 3.17.19

Got a really good idea about doing a hybrid coding model using embeddings. We start with a list of “place terms” and a list of “space terms”. We then use the embedded representation (vector) of those terms to find the adjacent terms. This is a sort of automated “snowball sampling”, where terms can lead to other terms. Once we have these terms, we use them as queries into the database to find the campaign and the timestamp for each. We use these to create the trajectories and maps.

This is a pretty straightforward code and a set of queries to write, and I have high confidence that it will work, and provide a novel, understandable method of producing a nice ‘mixed method’ process that is also grounded completely in the corpora.

Phil 3.15.19

7:00 – ASRC

  • Downloaded the JuryRoom spec from Waikato and sent my sympathies for Christchurch
  • Worked on getting cosine distance working – Done. Also created spreadsheets of the distances between posts and list the posts on a tab in the spreadsheet. I strip out the words that aren’t used to make the vectors so the posts look a little funny, but the gist is there:

Phil 3.14.19

ASRC AIMS 7:00 – 4:00, PhD ML, 4:30 –

Phil 3.13.19

7:00 – 5:00 ASRC AIMS

SAv3.13

  • Got the db reading in and creating PostAnalyzer objects for each user by channel
  • Need to also create a PostAnalyzer that contains the entire set of runs. Since that crosses DBs, I think the best way to do this is to create a method that lets me load additional data into an existing instance
    • Added load_data() method to PostAnalyzer. Seems to be working
    • The GUI code was getting ugly with the analytics, so I did some refactoring and now have an MVC architecture and am happier
  • Create the master embedding – done!!!! The number of points seems low (98), but I’ll look at that tomorrow.Embedding
  • Compare user average vectors in a user x user matrix
  • Compare post average vectors in a post x post matrix
  • Missed the JuryRoom Skype last night. Aaron was there though. Need to catch up
    • Quick notes for JuryRoom:
      • The votes should be for a posted response, not a yes/no to the original question
      • Groups should be able stick together if they want
      • Topics should be “threadable” for groups, with defined and randomized order
  • Steve S. Is going to read the paper and make suggestions
  • Here’s how you import into postgres: .\pg_restore.exe -h localhost -p 5433 -U postgres -d GEMSEC_logs -v “D:/Development/A2P/GEMSEC_logs/greatdb.backup”
  • Aaron’s blog is up!

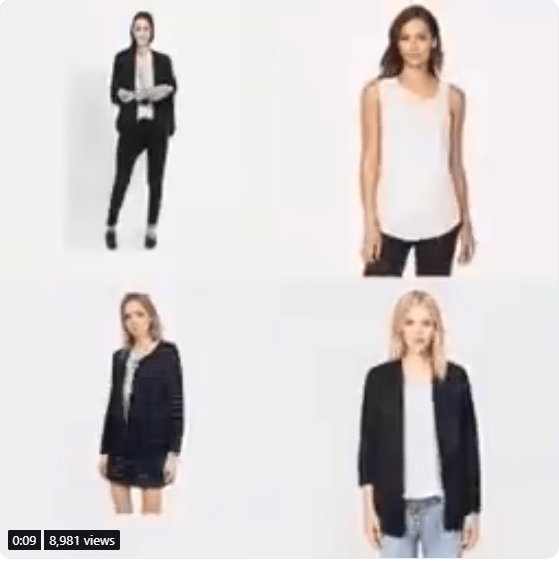
GAN_Fashion

Click to see trajectories through fashion space (paper)

Phil 3.12.19

7:00 – 4:00 ASRC PhD

TFK

d1dpqqlxgaansuo

Phil 3.11.19

7:00 – 10:00 ASRC PhD. Fun, long day.

Phil 3.10.19

Learning to Speak and Act in a Fantasy Text Adventure Game

  • We introduce a large scale crowdsourced text adventure game as a research platform for studying grounded dialogue. In it, agents can perceive, emote, and act whilst conducting dialogue with other agents. Models and humans can both act as characters within the game. We describe the results of training state-of-the-art generative and retrieval models in this setting. We show that in addition to using past dialogue, these models are able to effectively use the state of the underlying world to condition their predictions. In particular, we show that grounding on the details of the local environment, including location descriptions, and the objects (and their affordances) and characters (and their previous actions) present within it allows better predictions of agent behavior and dialogue. We analyze the ingredients necessary for successful grounding in this setting, and how each of these factors relate to agents that can talk and act successfully.

New run in the dungeon. Exciting!

Finished my pass through Antonio’s paper

Zoe Keating (May 1) or Imogen Heap (May 3)?

Phil 3.9.19

Understanding China’s AI Strategy

  • In my interactions with Chinese government officials, they demonstrated remarkably keen understanding of the issues surrounding AI and international security. It is clear that China’s government views AI as a high strategic priority and is devoting the required resources to cultivate AI expertise and strategic thinking among its national security community. This includes knowledge of U.S. AI policy discussions. I believe it is vital that the U.S. policymaking community similarly prioritize cultivating expertise and understanding of AI developments in China.

Russian Trolls Shift Strategy to Disrupt U.S. Election in 2020

  • Russian internet trolls appear to be shifting strategy in their efforts to disrupt the 2020 U.S. elections, promoting politically divisive messages through phony social media accounts instead of creating propaganda themselves, cybersecurity experts say.

Backup phone

Work on SASO paper – started

Rachel’s dungeon run is tomorrow! Maybe cross 10,000 posts?

Look at using BERT and the full Word2Vec model for analyzing posts

The Promise of Hierarchical Reinforcement Learning

  • To really understand the need for a hierarchical structure in the learning algorithm and in order to make the bridge between RL and HRL, we need to remember what we are trying to solve: MDPs. HRL methods learn a policy made up of multiple layers, each of which is responsible for control at a different level of temporal abstraction. Indeed, the key innovation of the HRL is to extend the set of available actions so that the agent can now choose to perform not only elementary actions, but also macro-actions, i.e. sequences of lower-level actions. Hence, with actions that are extended over time, we must take into account the time elapsed between decision-making moments. Luckily, MDP planning and learning algorithms can easily be extended to accommodate HRL.

Phil 3.7.19

Day 2 of the TF Dev summit. Worth the money, though much less research-y and more implementation and production-y

Google Cloud has Fedramp certification, which it does see details here.

Live Transcribe

Coral: On Device Transfer learning (paper)

TF 2.0 API \changes and Behavior changes

  • Best practices (link: )
  • Declare variables at the beginning of the code
  • Keras Functional API
    • The Keras functional API is the way to go for defining complex models, such as multi-output models, directed acyclic graphs, or models with shared layers.
  • Autograd can automatically differentiate native Python and Numpy code. It can handle a large subset of Python’s features, including loops, ifs, recursion and closures, and it can even take derivatives of derivatives of derivatives. It supports reverse-mode differentiation (a.k.a. backpropagation), which means it can efficiently take gradients of scalar-valued functions with respect to array-valued arguments, as well as forward-mode differentiation, and the two can be composed arbitrarily. The main intended application of Autograd is gradient-based optimization. For more information, check out the tutorial and the examples directory.
  • JAX is Autograd and XLA, brought together for high-performance machine learning research. With its updated version of Autograd, JAX can automatically differentiate native Python and NumPy functions. It can differentiate through loops, branches, recursion, and closures, and it can take derivatives of derivatives of derivatives. It supports reverse-mode differentiation (a.k.a. backpropagation) via grad as well as forward-mode differentiation, and the two can be composed arbitrarily to any order.
  • Effective TF 2.0: There are multiple changes in TensorFlow 2.0 to make TensorFlow users more productive. TensorFlow 2.0 removes redundant APIs, makes APIs more consistent (Unified RNNsUnified Optimizers), and better integrates with the Python runtime with Eager execution.

Phil 3.6.19

5:00 – ASRC TL

  • Got a lot done on the BAA on the flight yesterday
  • Wrote up a description of LMN and CM for Eric V.
  • Reading more of the Handbook of Latent Semantic Analysis. It’s giving me some good ideas for calculating similarities of posts using Word2Vec and comparing the average vector for each post
  • Antonio got an extension to the 12th. Need to see what he’s up to. Wow, there’s a lot there now. Made some comments about what I’d like to see. I’ll pull down the document to read later
  • Continued to tweak the slides
  • TF Dev conference main sessions today. Breakouts tomorrow.

Phil 3.4.19

7:00 – 5:00 ASRC

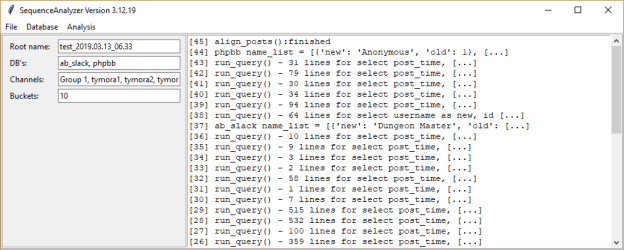
  • Build an interactive SequenceAnalyzer. The adjustments are
    • Number of buckets
    • Percentages for each analytic (percentages to keep/discard
    • Selectable skip words that can be added to a list (in the db?)
  • Algorithm
    1. Find the most common words across all groups, these are skip_words
    2. Find the most common words along the entire series of posts per player and eliminate them
    3. Find the most common/central words across all sequences and keep those as belief places
    4. For each sequence by group, find the most common/central words after the belief places. These are the belief spaces.
    5. Build an adjacency matrix of players, groups, places and spaces
    6. Build submatrices for centrality calculations? This could be rather than finding the most common
    7. Possible word2vec variations?
      1. It seems to me that I might be able to use direction cosines and dynamic time warping to calculate the similarity of posts and align them better than the overall scaling that I’m doing now. DM posts introducing a room should align perfectly, and then other scaling could happen between those areas of greatest alignment
  • Display
    • Menu:
      • Save spreadsheet (includes config, included words, posts(?), trajectories)
      • load data
      • select database
      • select group within db
      • load/save config file
      • clear all
    • Fields
      • percent for A1, A2, A3, A4
      • Centrality/Sum switch
      • BOW/TF-IDF switch
      • Word2vec switch?
    • Textarea (areas? tabbed?)
      • Table with rows as sequence step. Columns are grouped by places, spaces, groups, and players
    • Work on Antonio’s paper got a first draft on introduction and motivation
    • BAA
      • Upload latex and references to laptop
    • Haircut! Pack!
    • Model-Based Reinforcement Learning for Atari
      • Model-free reinforcement learning (RL) can be used to learn effective policies for complex tasks, such as Atari games, even from image observations. However, this typically requires very large amounts of interaction — substantially more, in fact, than a human would need to learn the same games. How can people learn so quickly? Part of the answer may be that people can learn how the game works and predict which actions will lead to desirable outcomes. In this paper, we explore how video prediction models can similarly enable agents to solve Atari games with orders of magnitude fewer interactions than model-free methods. We describe Simulated Policy Learning (SimPLe), a complete model-based deep RL algorithm based on video prediction models and present a comparison of several model architectures, including a novel architecture that yields the best results in our setting. Our experiments evaluate SimPLe on a range of Atari games and achieve competitive results with only 100K interactions between the agent and the environment (400K frames), which corresponds to about two hours of real-time play.


Phil 3.3.19

Once more, icky weather makes me productive

  • Ingested all the runs into the db. We are at 7,246 posts
  • Reworking the 5 bucket analysis
  • Building better ignore files and rebuilding bucket spreadsheets. It tuns out that for tymora1, names took up 25% of the BOW, so I increased the fraction saved to the trimmed spreadsheets to 50%
  • Building bucket spreadsheets and saving the centrality vector
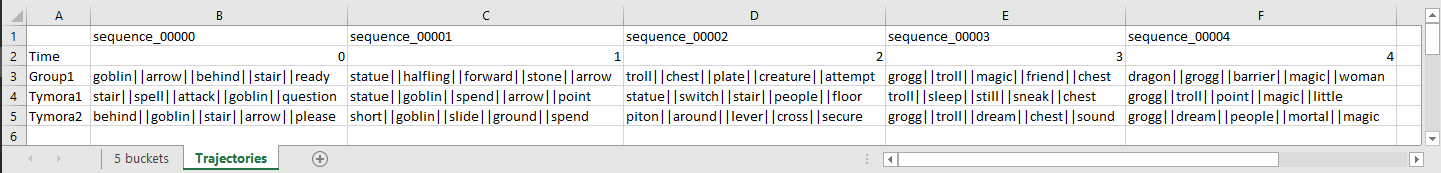
  • Here’s what I’ve got so far: ThreeRuns
  • Trajectories: Trajectories
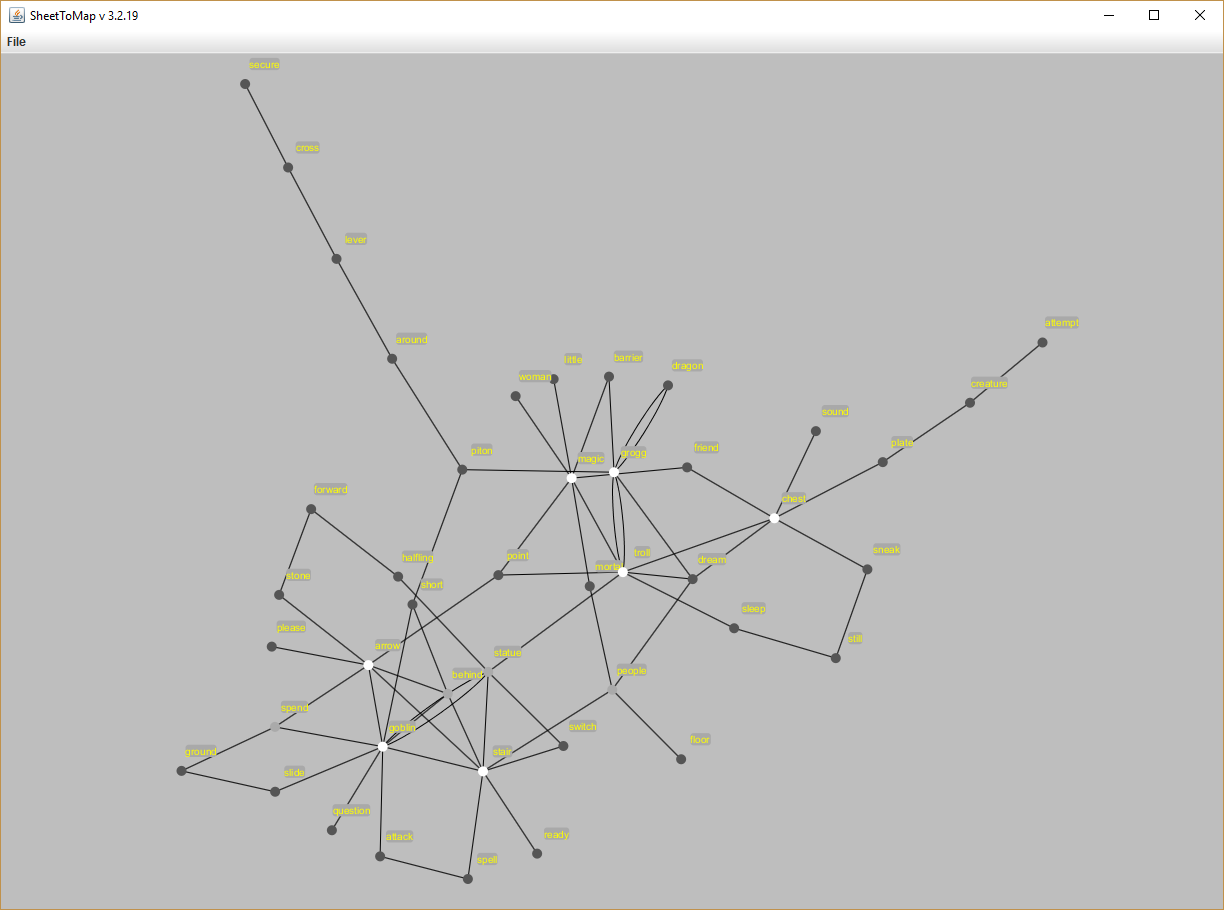
  • First map: firstMap
  • Here it is annotated: firstMapAnnotated
  • Some thoughts. I think this is still “zoomed out” too far. Changing the granularity should help some. I need to automate some of my tools though. The other issue is how I’m assembling my sequences.