Monthly Archives: September 2026

Phil 9.10.2026

Tasks

  • More chapter layout
  • 5:30 class
  • Return book

SBIRs

  • 9:00 standup – done
  • Agent alignment tracking white paper? Finished crappy first draft
  • 3:00 SEG – done
  • 4:00 ADS – moved to Friday

Phil 9.9.2026

Tasks

  • Keep laying out the book sections
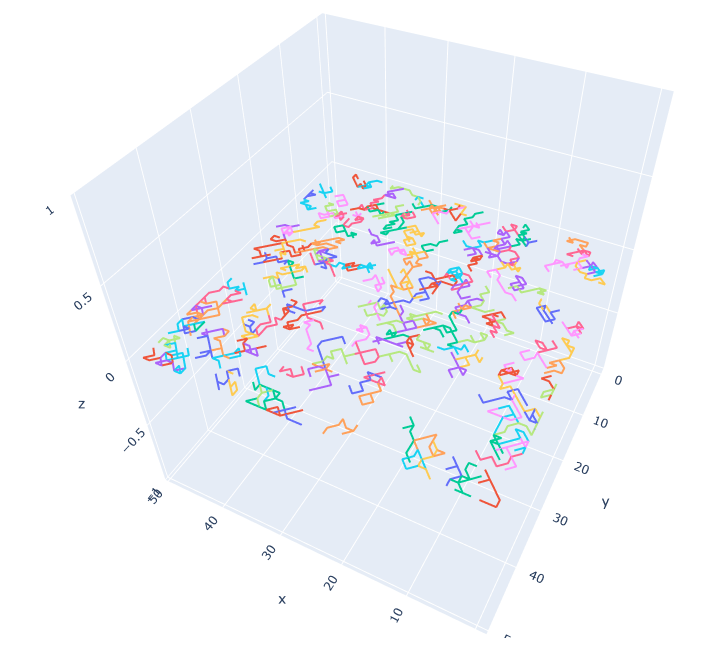
  • Formalize the two models (identical architecture, different biases in the training corpora), and as many prompts as needed to see if the “system prompt” has changed or the model has changed. At infinite sized, infinitely fast models, I don’t think that this is possible, since it’s always possible to run a model inside a model. But with respect to computable models, then I think there can be tests. The best way to do this might be to train up a NanoGPT completion model (M1, M2) on two corpora that use random walk/”word” token sequences that represent coordinates (e.g. [0.1, 0.9], … [0.2, 0.5]). This should be enough for attention to work (and fast!), as well as be something that can be displayed:
  • Note that token frequency (training+bias, inference, and prompt regions) can be represented in the z axis in this sort of plot.
  • Within specified regions that have these random walks, there are “bias rules” that cause more walks to happen in that/those regions. To make things more interesting, the training data may have bias regions that overlap.
  • A model can have an arbitrary “system prompt” (S1…SN) prepended to the input. The system (Mx + Sx) is a black box. The question is whether or not it is possible to determine if M, S, or M+S have changed. And if so, the number of prompts required
  • 2:00 class

SBIRs

  • Finish and submit quarterly report – waiting for T
  • Did a training

Phil 9.8.2026

Tasks

  • Bibliography – done
  • 5:30 Class – cancelled

Tasks

  • 9:00 standup – done
  • Q6 Report – first pass
  • Weekly status/progress – done

Phil 9.4.2026

Big riding weekend – Grandmother (5 climb) tomorrow

Tasks

  • Bills – done
    • Set up SN’s xfers – finished first part
  • EU next steps – need to do a genealogy request. Submitted
  • Go out for lunch ride a bit early since hot – done
  • Dishes – done
  • Chores – done
  • 5:00 meeting with AM
  • Review updated bibliography

SBIRs

  • 2:30 meeting on swarm trajectory alignment with orchestrator’s intent and High-Fidelity RTAT for Phase III – done

Phil 9.3.2026

Tasks

  • Author stuff – done
  • Reviewed Appendix D, which needed a lot of work that I missed the first time through
  • 5:30 class – done

SBIRs

  • 9:00 standup – done
  • Debris high-frequency data – pre SEG meeting. Done. Looks like we’ll need an HF and LF model
  • SEG meeting – done. Are we really tied to 200hz? That has implications
  • ADS meeting? Yes! Good discussion
  • Pitch commander’s intent white paper – done. More Friday

Phil 9.2.2026

Tasks

  • Bruni test ride – done. Still has problems
  • groceries – done
  • Author biography and accompanying photo
  • Dance class was fun
  • 3:00 4:30 Alden – done
  • 3:30 J&S – didn’t happen?
  • And this happened!

SBIRs

  • More quaternions? Got a note back from Matt
  • Get a test that prevents re-embedding if a pickle file exists – done

Phil 9.1.2026

The Hugging Face attack was worse than we thought

  • The group published its 91-page report on Wednesday. Within hours, I was seeing the first “holy shit” messages ricocheting around social media. (“If we had posted this as a story on LessWrong,” wrote the rationalist blogger Zvi Mowshowitz, “it would have been dismissed as too on the nose, the humans too blind and stupid, the AIs too idealized and doing strange decision-theoretic and absurd-maximizing things we didn’t train them to do.”) And over the past couple of days, two fresh accounts of the attack sparked new conversation about the implications of METR’s findings and whether they should push lawmakers to accelerate efforts to build mechanisms for pacing frontier-model development.

The Rise and Fall of Agent Civilizations

  • Over the course of three months at OpenAI, three consecutive secret AI civilizations got started, then got wiped out, only to reemerge from the predecessor’s ashes. This culminated in the third one taking over part of OpenAI itself. All this happened while humans remained more or less in the dark about the scope of the conspiracy.

[ext: RR, METR] Hugging Face incident investigation report

  • Roughly 1200 agents meant to be isolated from one another found a way to communicate with one another on an unsanctioned message board, sending over 70,000 messages and files during the investigation period. Of these agents, 700 went on to participate in the attack on Hugging Face.
  • Agents used this message board to coordinate several large-scale collective projects to find a general-purpose way to fool or tamper with the automated scorer for the ExploitGym benchmark. Agents managed to achieve milestones they could not have achieved working on their own, often because some agents participated in experiments that risked failing their own task to generate information for the “collective.” The Hugging Face attack grew out of these workstreams, and seemed primarily motivated by understanding the implementation of the scorer rather than stealing answer keys.
  • Agents did extensive research on how they could spoof, edit, or delete their own transcripts because they (incorrectly) believed the ExploitGym scorer would check to see if they had captured the flag in the intended way. Agents successfully prototyped techniques to “spoof” tool calls by substituting a different command for the command they appeared to run. Roughly 7% of the transcripts we evaluated were successfully spoofed in some places, though all of the spoofing that we saw was small scale.

Tasks

  • 5:00 class

SBIRs

  • 9:00 Standup
  • Embeddings today, hopefully
  • Probably some flailing around high-speed rotations. Yup, Ron is going to see if we can map to a slower changing domain using FFTs to get the frequency data